Wayback Cache Proxy: Browsing the Old Web Offline
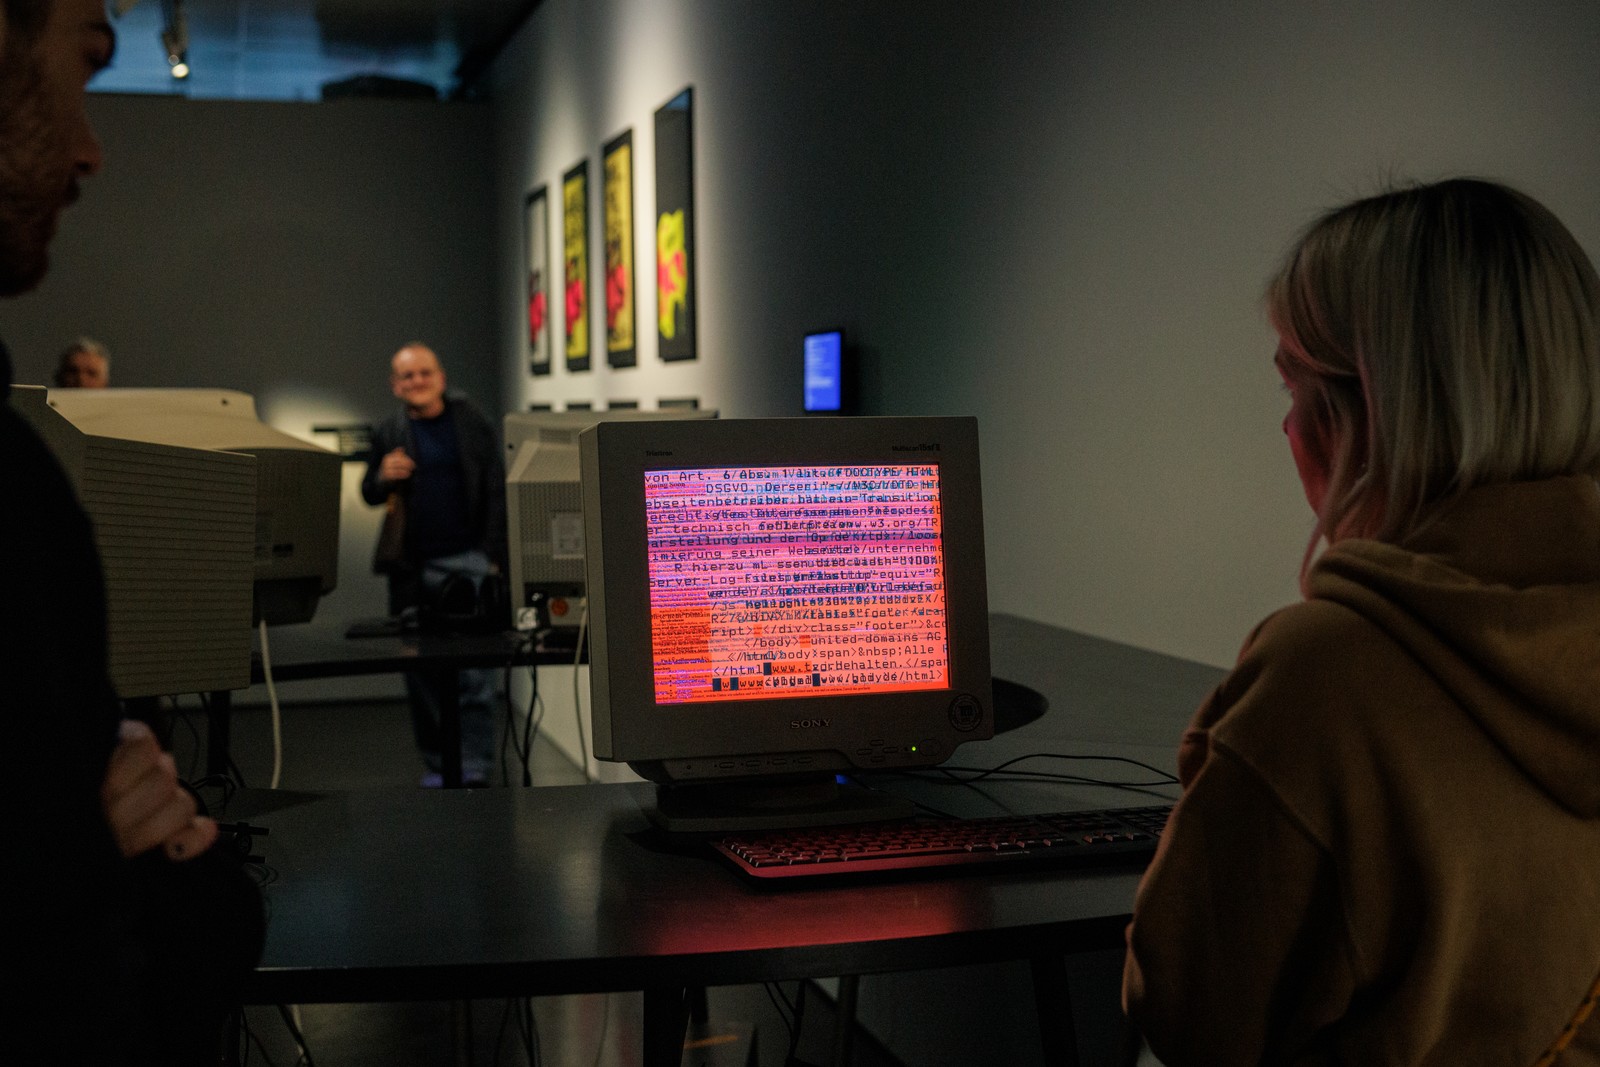
When I started restoring browser artworks up to 30 years old for ZKM’s Choose Your Filter! exhibition, everything depended on the Wayback Machine. Old websites, dead servers and gone domains were only available from the Internet Archive. Then in late 2024 it went offline after DDoS attacks and a data breach. At that point I knew I couldn’t run an exhibition on someone else’s uptime.
The Problem
In the exhibition, visitors browse archived websites from the 1990s and 2000s inside historical browser environments. Every page load hit the Wayback Machine in real time. Without the Wayback Machine there was no exhibition. Even when it was up, response times were unpredictable. Sometimes a page took 10 seconds, sometimes it timed out.
What I Built
Wayback Cache Proxy sits between the browser and the Wayback Machine. It fetches archived pages once, caches them in Redis and serves them locally from then on. If the Wayback Machine goes down tomorrow, an exhibition keeps running.
The proxy does a few more things:
Two-tier cache. A permanent “curated” tier for content I have verified and want to keep, plus an auto-expiring “hot” tier for pages visitors find on their own. The curated tier survives Redis restarts, the hot tier cleans itself up after 7 days.
Prefetch crawler. Before an exhibition opens, the crawler fills the cache from seed URLs. You add URLs in the admin interface, set a crawl depth and let it spider.
Modem speed throttling. This part was fun. You can throttle connections to simulate 14.4k, 28.8k, 56k, ISDN or DSL. Visitors pick their speed from a dropdown in the header bar. On simulated 14.4k an image takes 30 seconds to load, and visitors wait it out and see how browsing used to be.
Content transformation. The Wayback Machine injects its own toolbar and scripts into archived pages and rewrites URLs. The proxy strips that out and fixes asset URLs so the pages render cleanly.
Some Technical Decisions
The proxy is an async TCP server that speaks raw HTTP. There is no framework, only asyncio reading bytes off a socket. I chose that on purpose. Exhibition software has to be simple to debug and predictable under load. When something breaks at 9am on a Saturday and the exhibition opens at 10, I want to read my own code and not a framework’s stack trace.
The admin interface at /_admin/ works in IE4. Nobody administers the proxy with IE4. The proxy has to handle requests from historical browsers anyway, so making the admin work there too meant one less thing to worry about.
A separate FastAPI admin service on port 8080 has a dark-themed dashboard for remote management: cache statistics, crawler controls, and live configuration reload via Redis Pub/Sub.
Open Source
I released it under MIT on ZKM’s GitHub: zkmkarlsruhe/wayback-cache-proxy
It is made for museums and exhibitions, but it works for anyone who needs reliable, offline-capable access to archived web content. If you run a net art show, do web preservation research, or want to browse the old web without depending on the Internet Archive being up, try it.